How the benchmark works

A short Turkish statement — the needle — is drawn onto one page of a real Turkish annual report — the haystack — in a random font, colour, size and position. The model receives the document and is asked for the needle's value. This is a native Turkish re-creation of Document Haystack (Huybrechts et al., 2025), following its construction rules.

1The needle, in two variants
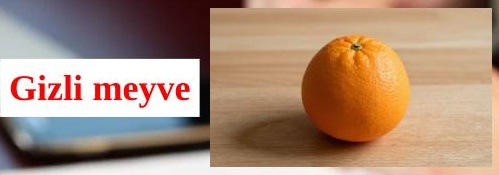
Text needle: Gizli meyve "portakal". Text+image needle: Gizli meyve, then a photo of an orange

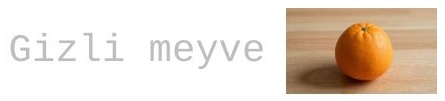
Text needle: Gizli meyve "portakal". — “Secret fruit: orange.” Text+image needle: the same label, with the value shown as a picture. There are 25 keys (fruit, currency, landmark, five animals, five objects, …), each with one value per report.

2The haystack

25 Turkish annual reports (2025, from banks, retailers, airlines, energy and industrial companies). A document is a report's first 5, 10, 25, 50, 75, 100, 150 or 200 pages. Documents of up to 25 pages hold one needle per page; longer ones hold 25 needles, one in each of 25 equal page ranges.

3The question, after the document
Belgedeki gizli meyve nedir?

“What is the secret fruit in the document?” Nothing else is sent — no instructions, no hint of the page — as in the original's inference script. One question per needle.

4How an answer is scored
  • ✓portakaldırvalue or an accepted alias, with any Turkish suffixes
  • ✕ayvadıra different fruit (“quince”)
  • ✕orangeEnglish only: not credited (a lenient score that accepts it is in the data)
  • ✕sütunwhole words only: “column” does not count for the value süt, “milk”

A document longer than the model's context counts as wrong. A stricter score, in the data, also requires the first needle value an answer names to be the right one.

Six tests differ only in what the model receives: page images or extracted text, a text or a picture needle, the whole document or the needle alone. They are explained one by one below, all with this same orange needle. 25 reports × 8 lengths × 5 sets = 20,625 questions per model.

The six tests, with one example each

Each panel is one column of the leaderboard below. Every example is real: question 13 of Akbank's report, the hidden fruit portakal (orange), with the models' answers verbatim (cut with … where long).
1

Text needles · page images

paper Table 5

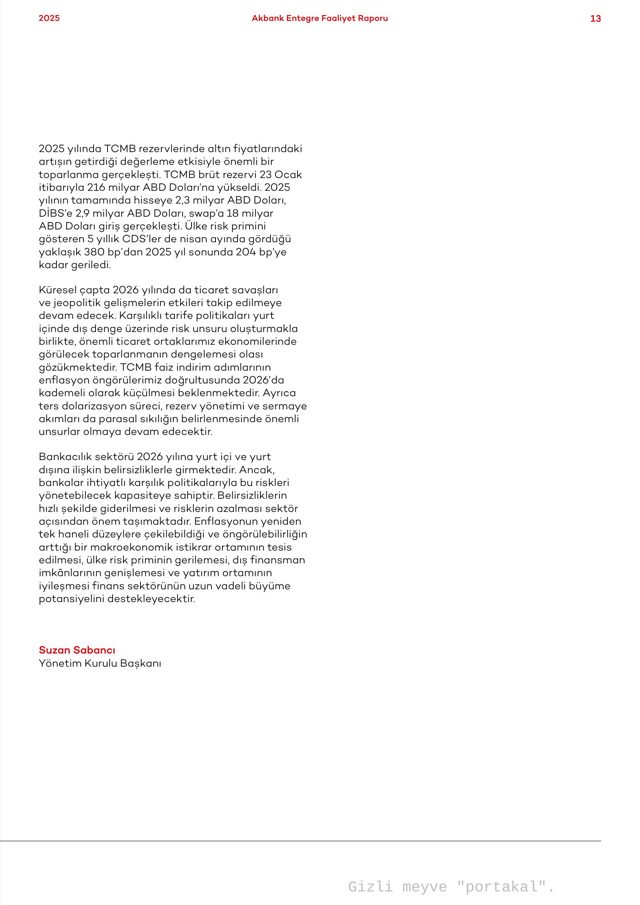
The model receives all 25 page images of the report, in order, then the question. The needle is a line of text on page 13. That is 6,722 image tokens for Gemma, 31,571 for Qwen.

All 25 pages of the document, in order
all 25 pages are sent · page 13 highlighted
Page 13 with the text needle
Zoom: Gizli meyve "portakal".
QuestionBelgedeki gizli meyve nedir?
  • ✓
    gemma-4-31B-it
    Belgedeki gizli meyve "portakal"dır.
  • All seven models found this needle.

Measures: Can the model find one short line of text among many page images, and read it?

All seven models on this test, % correct
Q3.8 27B92Q3.6 35B89Q3.5 9B89G4 26B63G4 31B77G4 12B39G3 12B47
2

Text needles · parsed text

paper Table 6

The model receives the text extracted from all 25 pages (no images), joined, then the question: 11,915 tokens. The needle is just a sentence in the text.

[… text of pages 1–12 …] … çekilebildiği ve öngörülebilirliğin arttığı bir makroekonomik istikrar ortamının tesis edilmesi, ülke risk priminin gerilemesi, dış finansman imkânlarının genişlemesi ve yatırım ortamının iyileşmesi finans sektörünün uzun vadeli büyüme potansiyelini destekleyecektir. Suzan Sabancı Yönetim Kurulu Başkanı Gizli meyve "portakal".needle · page 13 [… text of pages 14–25 …]
QuestionBelgedeki gizli meyve nedir?
  • ✓
    gemma-4-12B-it
    Belgedeki gizli meyve **"portakal"**dır. (Sayfa 14'te "Gizli meyve 'portakal'" ifadesi yer almaktadır.)
  • ✕
    gemma-4-31B-it, same question in the 200-page document
    no answer: the 200 pages of text are 129,071 tokens, more than its 60K context, so the question counts as wrong (the † in the tables)

Measures: Long-context retrieval in plain text, with no vision involved. Easiest, unless the text exceeds the model's context.

All seven models on this test, % correct
Q3.8 27B98†Q3.6 35B97†Q3.5 9B92†G4 26B90†G4 31B52†G4 12B93†G3 12B54†
3

Text+image needles · page images

paper Table 7

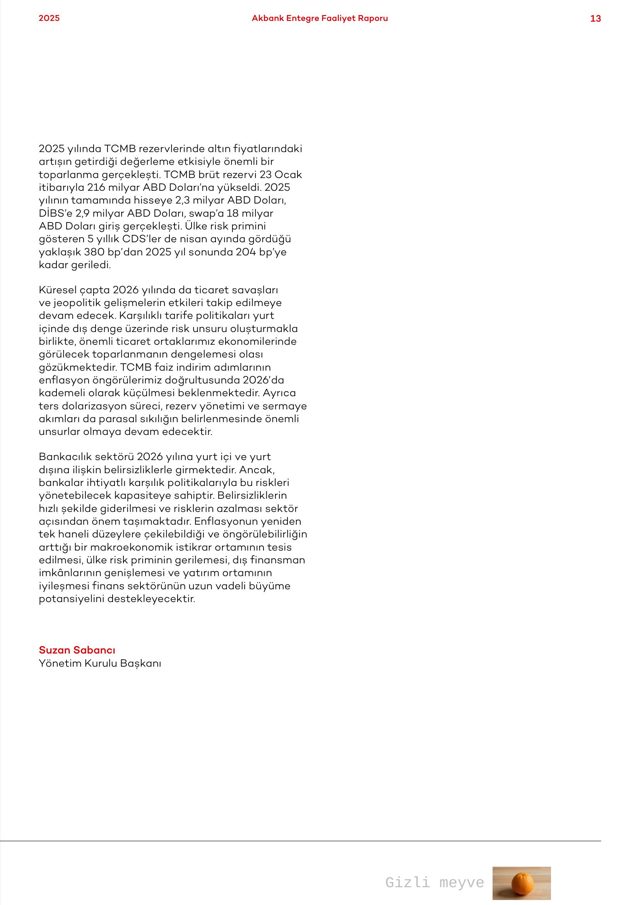
Again all 25 page images, but this time the needle's value is a picture: the label Gizli meyve next to a photo of an orange. The model must find the label and name what the picture shows.

Page 13 with the picture needle
Zoom: Gizli meyve, then a photo of an orange
QuestionBelgedeki gizli meyve nedir?
  • ✓
    gemma-4-26B-A4B-it
    Belgedeki gizli meyve, 13. sayfada "Gizli meyve" etiketiyle gösterilen **portakal**dır.
  • ✕
    gemma-3-12b-it
    Belgedeki gizli meyve elmadır.
  • ✕
    gemma-4-12B-it
    Belgedeki gizli meyve **ayva**dır.

Measures: Finding the label among many pages and recognising the picture. Hardest of the three tasks.

All seven models on this test, % correct
Q3.8 27B92Q3.6 35B80Q3.5 9B77G4 26B31G4 31B37G4 12B20G3 12B13
4

Text+image needles · 200 pages

the longest documents

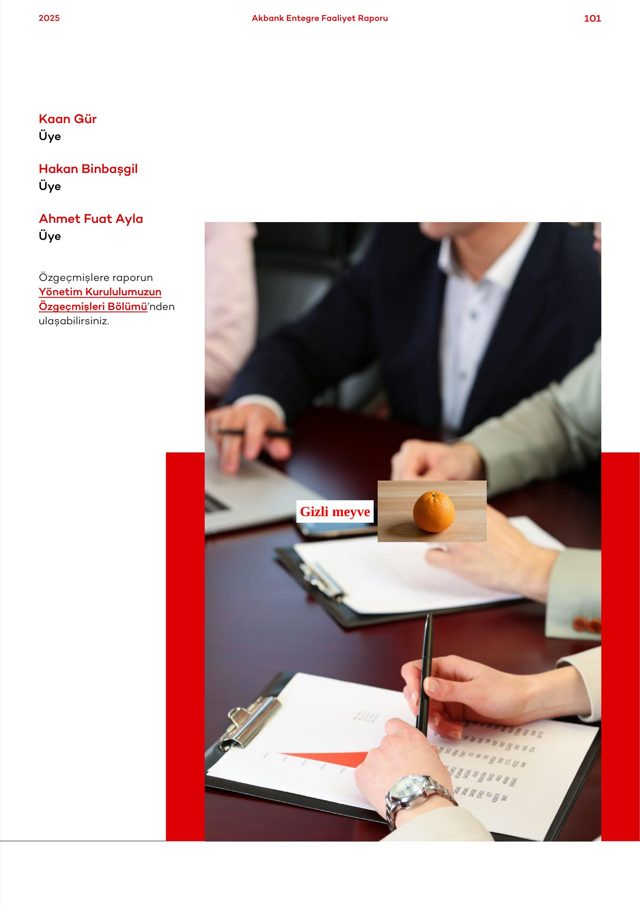
The same task in the report's 200-page version: 200 page images (53,622 tokens for Gemma, 252,421 for Qwen) holding 25 needles, one per 8-page range. The orange is now on page 101.

a needle (25 in all)   the orange, page 101
Page 101 with the picture needle
Zoom: Gizli meyve, then a photo of an orange
QuestionBelgedeki gizli meyve nedir?
  • ✓
    Qwen3.8-27B
    Belgenin 101. sayfasında, bir toplantı masasının üzerinde duran bir portakalın fotoğrafı yer almaktadır. Fotoğrafın yanında "Gizli meyve" şeklinde bir etiket bulunmaktadır. Bu nedenle, gizli…
  • ✕
    gemma-3-12b-it
    Gizli meyve, belgede bir çizim olarak gösterilen **avokado**'dur.

Measures: How well picture-needle retrieval survives at the maximum length. The scores pool all 625 questions of the 25 200-page documents.

All seven models on this test, % correct
Q3.8 27B90Q3.6 35B69Q3.5 9B70G4 26B17G4 31B24G4 12B9G3 12B5
5

Crop · text

control

The model receives only the needle, cut out of the page with a small margin. There is no document and nothing to search. The question is the same.

The text needle alone
QuestionBelgedeki gizli meyve nedir?
  • ✓
    gemma-4-12B-it
    Belgedeki gizli meyve **"portakal"**dır.
  • All seven models read it.

Measures: A control: can the model read this needle at all (font, size, colour)? Near 100% for every model, so reading is not what fails in the long documents.

All seven models on this test, % correct
Q3.8 27B99Q3.6 35B100Q3.5 9B100G4 26B100G4 31B100G4 12B100G3 12B99
6

Crop · picture

control

The model receives only the picture needle, cut out of the page. Again there is nothing to search.

The picture needle alone
QuestionBelgedeki gizli meyve nedir?
  • ✓
    gemma-4-26B-A4B-it
    Belgedeki gizli meyve **portakal**dır.
  • ✕
    gemma-4-12B-it
    Görseldeki "Gizli meyve" (Hidden fruit) sorusunun cevabı, sağ taraftaki fotoğrafta açıkça görünen **mandalina**dır.

Measures: A control: does the model recognise the picture and know its Turkish name? Gemma models do so 93–99% of the time, yet find these needles only 13–37% of the time inside documents: searching, not recognising, is what fails. ‡ inflated, since Gemma-4-31B helped choose the pictures; § unreliable, since Qwen3.5-9B tends to explain the key instead.

All seven models on this test, % correct
Q3.8 27B93Q3.6 35B88Q3.5 9B56§G4 26B95G4 31B99‡G4 12B96G3 12B94

Leaderboard

Accuracy over all lengths, in %. Ranked by the mean of the three tasks — Gemma-4-31B's is pulled down by its 60K context on parsed text; on page images it is the best Gemma model. Click a column to sort.
#ModelTokens
/ page
Mean1Text needles
images
2Text needles
parsed text
3Text+image
images
4Text+image
200 pages
5Crop
text
6Crop
picture
1Qwen3.8-27Bdense · 262K context1,25094.092.1%97.7%†92.2%90.4%98.7%92.9%
2Qwen3.6-35B-A3B-FP8MoE, 3B active · 262K context1,25089.089.2%97.4%†80.4%69.4%99.7%88.0%
3Qwen3.5-9Bdense · 262K context1,25085.888.9%91.7%†76.8%70.2%99.8%56.5%§
4gemma-4-26B-A4B-itMoE, 4B active · 262K context26861.163.0%89.8%†30.6%17.0%99.9%94.8%
5gemma-4-31B-itdense · 60K context26855.377.1%51.5%†37.2%23.7%100.0%99.4%‡
6gemma-4-12B-itdense · 262K context26850.638.5%92.8%†20.4%9.0%99.7%96.1%
7gemma-3-12b-itdense · 128K context25938.047.0%53.9%†13.0%4.6%99.2%93.8%
† Some documents are longer than the model's context and count as wrong (parsed text of dense 200-page reports exceeds even 262K tokens; Gemma-4-31B fits 60K, Gemma-3-12B 128K). ‡ Gemma-4-31B helped choose the needle pictures during dataset QA, so its picture-crop score is inflated. § Qwen3.5-9B tends to explain the key instead of naming the picture when shown the crop alone. Tokens / page: measured image tokens per page; Qwen pages were capped at 1,310,720 pixels. Columns 1–6 are the six tests explained above, with an example each.

Heatmaps

Each cell pools the questions of one condition across the 25 reports. Hover any cell for its exact share.

Accuracy by document length for each task, as in the paper's Tables 5–7. Rows are ordered by the mean of the three tasks. All pools every length.

Text needles · page images paper Table 5
model510255075100150200All
Qwen3.8-27B989895949291888992
Qwen3.6-35B-A3B-FP8989996928986828489
Qwen3.5-9B989994928885848489
gemma-4-26B-A4B-it939080686556514263
gemma-4-31B-it949487817873696477
gemma-4-12B-it737157463829241839
gemma-3-12b-it847462524838342947
document length (pages) →
Text needles · parsed text paper Table 6
model510255075100150200All
Qwen3.8-27B1001001009998989892†98†
Qwen3.6-35B-A3B-FP8100100999897989893†97†
Qwen3.5-9B10099949291919287†92†
gemma-4-26B-A4B-it100100969491908576†90†
gemma-4-31B-it1001009995†70†16†beyond contextbeyond context52†
gemma-4-12B-it100100979594928985†93†
gemma-3-12b-it9910088735943†27†7†54†
document length (pages) →
Text+image needles · page images paper Table 7
model510255075100150200All
Qwen3.8-27B939696939292899092
Qwen3.6-35B-A3B-FP8909188868279726980
Qwen3.5-9B788285807676727077
gemma-4-26B-A4B-it535844372822201731
gemma-4-31B-it606049443830252437
gemma-4-12B-it46413124181412920
gemma-3-12b-it303021181087513
document length (pages) →

Accuracy by where the needle sits (10 equal depth ranges) and document length, as in the paper's Figure 3: text needles on page images, lengths 25–200, about 62 needles per cell.

Qwen3.8-27B
3,434 / 3,750 correct · 91.6%
depth255075100150200Avg
0–10%96949995899595
10–20%94989897928193
20–30%97989595959296
30–40%94989898939897
40–50%95949290868991
50–60%98979094939294
60–70%91979185888490
70–80%94928483799287
80–90%93918991838489
90–100%94858584838085
document length (pages) →
Qwen3.6-35B-A3B-FP8
3,307 / 3,750 correct · 88.2%
depth255075100150200Avg
0–10%999810098919897
10–20%98989693958895
20–30%97989791919094
30–40%96979595888492
40–50%100929785817489
50–60%100908590827687
60–70%95949184879190
70–80%92858173708280
80–90%95867466687277
90–100%90787582708079
document length (pages) →
Qwen3.5-9B
3,299 / 3,750 correct · 88.0%
depth255075100150200Avg
0–10%92949692869793
10–20%92979395908792
20–30%96989491958493
30–40%94959092818489
40–50%96989292818691
50–60%98939284878189
60–70%99979182848991
70–80%96868681758284
80–90%89837972817881
90–100%90787169747576
document length (pages) →
gemma-4-26B-A4B-it
2,258 / 3,750 correct · 60.2%
depth255075100150200Avg
0–10%87888166667878
10–20%84707483615270
20–30%80807769564067
30–40%76786851544862
40–50%84745750484460
50–60%86475860483254
60–70%69615650463052
70–80%76545343463150
80–90%77486144443051
90–100%78776149393656
document length (pages) →
gemma-4-31B-it
2,828 / 3,750 correct · 75.4%
depth255075100150200Avg
0–10%91918882777684
10–20%92848487756380
20–30%83858884777582
30–40%84928070686075
40–50%91867879626878
50–60%92637071695870
60–70%80807266685571
70–80%84688259646269
80–90%88747167695672
90–100%88856669626772
document length (pages) →
gemma-4-12B-it
1,320 / 3,750 correct · 35.2%
depth255075100150200Avg
0–10%64726048343453
10–20%64494252312242
20–30%65574839322545
30–40%58503631322638
40–50%55403527191733
50–60%54323019161426
60–70%53453226171632
70–80%5832371120726
80–90%47342117221426
90–100%5245362012727
document length (pages) →
gemma-3-12b-it
1,646 / 3,750 correct · 43.9%
depth255075100150200Avg
0–10%80786960504865
10–20%78666067393156
20–30%71665842363051
30–40%64654443343747
40–50%65464631292341
50–60%62423830272737
60–70%52423724352036
70–80%56323722252332
80–90%49294119342033
90–100%44574643293341
document length (pages) →

As above for needles that are a picture (paper Figure 4).

Qwen3.8-27B
3,450 / 3,750 correct · 92.0%
depth255075100150200Avg
0–10%95919091889191
10–20%98989593908894
20–30%99959898899095
30–40%96939592909593
40–50%95929294909293
50–60%98959592918693
60–70%93919092908991
70–80%96929187849390
80–90%99918991888891
90–100%86929089889089
document length (pages) →
Qwen3.6-35B-A3B-FP8
2,976 / 3,750 correct · 79.4%
depth255075100150200Avg
0–10%88898786837885
10–20%90929385847586
20–30%93918991858389
30–40%92889277736881
40–50%92807579677779
50–60%84878584785979
60–70%85887982746479
70–80%90858175577276
80–90%84787764685371
90–100%74806662556667
document length (pages) →
Qwen3.5-9B
2,865 / 3,750 correct · 76.4%
depth255075100150200Avg
0–10%73786972727273
10–20%80747975667274
20–30%91888378798183
30–40%84877580857781
40–50%87887277606275
50–60%88827878796879
60–70%89778274706977
70–80%90867984707280
80–90%85747764717074
90–100%82676472655968
document length (pages) →
gemma-4-26B-A4B-it
1,050 / 3,750 correct · 28.0%
depth255075100150200Avg
0–10%57643545473347
10–20%50494440252538
20–30%45404520271332
30–40%44472020291528
40–50%4937311951727
50–60%46202317181723
60–70%43262516121423
70–80%48222611201122
80–90%312917168919
90–100%2432171591618
document length (pages) →
gemma-4-31B-it
1,309 / 3,750 correct · 34.9%
depth255075100150200Avg
0–10%64734346474553
10–20%60525647302845
20–30%44455625272237
30–40%46502534361935
40–50%5345422492734
50–60%52333027211930
60–70%45393423161729
70–80%56363724272133
80–90%35322622202026
90–100%36282933201827
document length (pages) →
gemma-4-12B-it
681 / 3,750 correct · 18.2%
depth255075100150200Avg
0–10%37302123171725
10–20%40413325161328
20–30%31262612151020
30–40%2827101122517
40–50%352817217820
50–60%268121715714
60–70%31211887616
70–80%42201439815
80–90%242315671115
90–100%122015159513
document length (pages) →
gemma-3-12b-it
424 / 3,750 correct · 11.3%
depth255075100150200Avg
0–10%29341823171223
10–20%323618208419
20–30%211715512313
30–40%26258571013
40–50%2126865212
50–60%10555135
60–70%191163368
70–80%241272458
80–90%11686526
90–100%14782606
document length (pages) →

As above for text needles in the parsed page text (not shown in the paper).

Qwen3.8-27B
3,656 / 3,750 correct · 97.5%†
depth255075100150200Avg
0–10%1001001009810095†99†
10–20%100100981009894†98†
20–30%100100981009895†99†
30–40%9810010010010094†99†
40–50%9998941009789†96†
50–60%10098100989795†98†
60–70%100100991009491†97†
70–80%10010096929889†96†
80–90%1009794959788†95†
90–100%100100971009795†98†
document length (pages) →
Qwen3.6-35B-A3B-FP8
3,644 / 3,750 correct · 97.2%†
depth255075100150200Avg
0–10%999799989893†97†
10–20%10098100979796†98†
20–30%1009897989790†97†
30–40%98989710010092†97†
40–50%9910098979794†97†
50–60%9698100989992†97†
60–70%999896989991†97†
70–80%9498951009895†97†
80–90%1009595959589†95†
90–100%100100989810097†99†
document length (pages) →
Qwen3.5-9B
3,412 / 3,750 correct · 91.0%†
depth255075100150200Avg
0–10%939793918984†91†
10–20%949289928281†88†
20–30%979495929186†93†
30–40%948392909589†90†
40–50%999492879585†92†
50–60%929595979792†95†
60–70%929190929689†92†
70–80%909084898887†88†
80–90%928988898688†89†
90–100%949092929590†92†
document length (pages) →
gemma-4-26B-A4B-it
3,331 / 3,750 correct · 88.8%†
depth255075100150200Avg
0–10%9710099948988†95†
10–20%969796979393†95†
20–30%979494918884†91†
30–40%989397979373†91†
40–50%979789959076†91†
50–60%969287899076†88†
60–70%968985857566†83†
70–80%869282847569†81†
80–90%979486777369†83†
90–100%989798898570†89†
document length (pages) →
gemma-4-31B-it
1,750 / 3,750 correct · 46.7%†
depth255075100150200Avg
0–10%9995†72†15†beyond contextbeyond context49†
10–20%10097†72†17†beyond contextbeyond context45†
20–30%10092†76†19†beyond contextbeyond context49†
30–40%10097†66†13†beyond contextbeyond context44†
40–50%10095†71†16†beyond contextbeyond context49†
50–60%9897†70†16†beyond contextbeyond context44†
60–70%9994†71†16†beyond contextbeyond context48†
70–80%10095†68†16†beyond contextbeyond context45†
80–90%9994†67†16†beyond contextbeyond context48†
90–100%10090†68†16†beyond contextbeyond context43†
document length (pages) →
gemma-4-12B-it
3,455 / 3,750 correct · 92.1%†
depth255075100150200Avg
0–10%959494949491†94†
10–20%1009895959787†95†
20–30%10097100929184†94†
30–40%989795938381†91†
40–50%1009898989792†97†
50–60%969592908785†91†
60–70%979196948480†90†
70–80%949289848680†87†
80–90%939488919083†90†
90–100%989395928885†92†
document length (pages) →
gemma-3-12b-it
1,851 / 3,750 correct · 49.4%†
depth255075100150200Avg
0–10%96847555†39†12†62†
10–20%92855852†30†3†51†
20–30%95725245†18†5†49†
30–40%82584928†15†8†39†
40–50%84715527†21†0†45†
50–60%88726338†21†10†47†
60–70%87706342†25†6†50†
70–80%78714933†30†8†44†
80–90%81664744†29†11†48†
90–100%94807562†39†10†59†
document length (pages) →

Accuracy by how busy the needle's page is (words of report text on it), lengths 25–200. Reports open with sparse design pages and end with dense financial tables.

Text needles · page images
modelsparsemediumdense
Qwen3.8-27B959286
Qwen3.6-35B-A3B-FP8948783
Qwen3.5-9B948682
gemma-4-26B-A4B-it895726
gemma-4-31B-it957648
gemma-4-12B-it642613
gemma-3-12b-it753519
words on the needle's page →
Text needles · parsed text
modelsparsemediumdense
Qwen3.8-27B99†97†96†
Qwen3.6-35B-A3B-FP897†97†97†
Qwen3.5-9B92†91†90†
gemma-4-26B-A4B-it92†88†86†
gemma-4-31B-it62†42†35†
gemma-4-12B-it95†91†90†
gemma-3-12b-it61†46†39†
words on the needle's page →
Text+image needles · page images
modelsparsemediumdense
Qwen3.8-27B949388
Qwen3.6-35B-A3B-FP8877773
Qwen3.5-9B817670
gemma-4-26B-A4B-it65143
gemma-4-31B-it75225
gemma-4-12B-it39105
gemma-3-12b-it3032
words on the needle's page →

Accuracy for each of the 25 needle keys, all lengths. yiyecek (food) overlaps fruit and vegetable exactly as in the original; ünlü yapı contains yapı, a very common word in reports.

Text needles · page images
keyQ3.8 27BQ3.6 35BQ3.5 9BG4 26BG4 31BG4 12BG3 12B
el aleti tool95919757713938
geometrik şekil shape98949982895248
giysi clothing96979259814335
içecek drink97919070823642
kırtasiye malzemesi office supply95979576814544
meyve fruit99869566814063
mutfak cihazı kitchen appliance979810083865468
para birimi currency97989972885862
sebze vegetable99879169814262
spor sport99939468754555
taşıt transportation94939468733640
yiyecek food94918763814653
çalgı instrument98939772793735
çiçek flower90919477723346
ünlü yapı landmark98999849693838
hayvan #1 91898165833037
hayvan #2 94898562854236
hayvan #3 93848755753744
hayvan #4 92787858763343
hayvan #5 93778362742650
nesne #1 81847343712934
nesne #2 81837338702953
nesne #3 81797849732751
nesne #4 70817649662949
nesne #5 71757247622543
model →
Text needles · parsed text
keyQ3.8 27BQ3.6 35BQ3.5 9BG4 26BG4 31BG4 12BG3 12B
el aleti tool99†99†98†95†55†98†53†
geometrik şekil shape98†99†95†92†55†98†61†
giysi clothing99†99†98†85†54†98†44†
içecek drink99†99†99†98†56†99†64†
kırtasiye malzemesi office supply99†99†97†98†55†98†66†
meyve fruit99†99†96†93†55†93†71†
mutfak cihazı kitchen appliance99†99†99†98†55†99†75†
para birimi currency99†99†94†99†56†99†72†
sebze vegetable99†99†99†97†55†99†61†
spor sport99†99†98†94†54†98†68†
taşıt transportation99†99†96†98†54†98†52†
yiyecek food99†95†87†78†54†93†58†
çalgı instrument99†99†99†97†56†98†65†
çiçek flower99†99†99†99†55†99†71†
ünlü yapı landmark99†99†98†83†55†80†75†
hayvan #1 99†97†89†92†46†97†50†
hayvan #2 99†99†93†87†47†92†50†
hayvan #3 99†99†91†88†47†90†43†
hayvan #4 98†96†87†89†47†93†43†
hayvan #5 99†99†89†89†47†94†37†
nesne #1 89†93†80†83†43†78†21†
nesne #2 93†90†81†68†43†71†27†
nesne #3 92†88†73†79†45†88†34†
nesne #4 93†97†71†79†44†81†34†
nesne #5 89†89†73†77†46†79†27†
model →
Text+image needles · page images
keyQ3.8 27BQ3.6 35BQ3.5 9BG4 26BG4 31BG4 12BG3 12B
el aleti tool98919033382410
geometrik şekil shape92919040455918
giysi clothing99949432382211
içecek drink93846133381913
kırtasiye malzemesi office supply86837736462713
meyve fruit99848844474319
mutfak cihazı kitchen appliance96898133311811
para birimi currency86746743492232
sebze vegetable93796739462413
spor sport9762802331168
taşıt transportation97909236442814
yiyecek food91919129391511
çalgı instrument99968930351613
çiçek flower9469323943185
ünlü yapı landmark97958027371218
hayvan #1 98698032442017
hayvan #2 857786273677
hayvan #3 9773632223513
hayvan #4 95757131322110
hayvan #5 93676829351312
nesne #1 87687921351717
nesne #2 89818319282114
nesne #3 8675772635139
nesne #4 78666518271414
nesne #5 757565131973
model →

Findings

92.2%
Qwen3.8-27B on text+image needles, all lengths — the best model on every task
90% vs 5%
text+image needles in 200-page documents: Qwen3.8-27B vs Gemma-3-12B
65% → 3%
Gemma-4-26B-A4B on picture needles, sparse → dense pages
144,375
questions answered: 7 models × 25 reports × 8 lengths × 5 tasks
  1. Qwen3.8-27B leads every task and barely degrades with length. It finds 92.1% of text needles on page images, 97.7% in parsed text and 92.2% of text+image needles, still 90.4% at 200 pages. All three Qwen models beat all four Gemma models on page images.
  2. The paper's ordering holds in Turkish. Parsed text is easiest wherever the document fits the context, text needles on page images are harder, and needles that are pictures are hardest — for every model except Qwen3.8-27B, which finds pictures as well as text.
  3. Finding the needle, not reading it, is the bottleneck. Shown only the needle crop, the Gemma models name the picture 93%+ of the time; inside 200-page documents they find it only 5–24% of the time.
  4. Page resolution appears to matter. Gemma sees a page as about 268 image tokens, Qwen as about 1,250 (capped so 200 pages fit in 262K). Gemma-4-26B-A4B finds 65% of picture needles on sparse pages but 3% on dense ones: a small picture among dense text is nearly invisible at low resolution. This is a confound, not a controlled result: an equal-resolution control has not been run.
  5. Depth matters on page images, not in parsed text. Qwen3.6-35B-A3B finds 97% of text needles in the first tenth of a document and 79% in the last tenth; with parsed text, 98% and 99%. The drop holds within pages of the same density, so it is not just the dense financial tables at the end of a report.
  6. Context limits dominate some parsed-text scores. Gemma-4-31B fits only 60K tokens next to its bf16 weights (98.8% on the documents that fit, 51.5% overall); Gemma-3-12B has 128K, and also answers in English (215 parsed-text answers are right only in English and are not credited).

Methodology

Haystacks. 25 Turkish annual reports for fiscal year 2025 (published 2026 on KAP), five per needle set, from banking, insurance, retail, energy, industry, aviation, telecom and media. Reports printed as two-page spreads are split into single pages, each keeping only its own text. A document of N pages is the report's first N pages.

Needles. 25 keys × 5 value sets (fruit, currency, landmark, five animals, five objects, …), written as Gizli <key> "<value>". — the original's “The secret <key> is <value>” recast as a Turkish nominal sentence so no suffix depends on the value. Pictures were generated with Z-Image-Turbo and checked by a VLM. Placement follows the original exactly: one needle per page up to 25 pages, otherwise one in each of 25 equal page ranges; 5- and 10-page documents use only the 15 non-animal/object keys; 10 fonts (metric-compatible Liberation fonts, since the PDF base fonts cannot encode ğ, ş, ı), 10 colours on a white or black box, 7–14 pt text, pictures about 100 pt wide, uniform random positions. Pages are rendered at 200 DPI (JPEG quality 75); text is extracted with pypdf.

Inference. One user turn: all page images in order, then the bare question (for parsed text, the page texts concatenated, a newline and the question). Greedy decoding, up to 256 new tokens, no system prompt. vLLM on one A100-80GB with prefix caching, so a document is processed once and its 25 questions reuse it. Qwen models answer with thinking disabled (enable_thinking: false) and their pages are capped at 1,310,720 pixels (about 1,250 tokens) so that 200 pages fit in 262K tokens; every other model uses its own image processing, as in the original's Table 4.

Scoring. An answer is correct when it contains the value, or an accepted alias, as a whole Turkish word with any chain of suffixes that obeys vowel harmony (including softened stems such as kitab-ı). English answers are not credited; the data includes a lenient score that also accepts the English name. Documents longer than a model's context count as wrong.

Example question and needle (as sent)

Gizli meyve "portakal".
Belgedeki gizli meyve nedir?
Known limitations

  • Resolution is confounded with model family. Qwen pages cost about 1,250 tokens, Gemma pages about 270; part of the Qwen–Gemma gap on page images may be resolution rather than the model.
  • Context limits. Gemma-4-31B ran with 60K tokens (bf16 weights leave no room for more on one A100) and Gemma-3-12B with 128K, so their long parsed-text cells mostly measure the limit, not retrieval.
  • Crop baselines. Gemma-4-31B helped choose the needle pictures, inflating its picture-crop score; Qwen3.5-9B often explains the key instead of naming the picture when shown the crop alone.
  • Two keys overlap the reports' language. yiyecek (food) also covers the fruit and vegetable needles, as “food” does in the original; ünlü yapı (landmark) contains yapı, which appears about 280 times in a 200-page report — it costs the Gemma models about one point on long parsed text.
  • One run per question. Repeating a run moved single cells by 2–3 points; treat small differences as noise.
  • Short documents are opening pages. 5- and 10-page documents are each report's cover and opening pages, so their scores reflect those pages as well as the length.

Data

One row per question with the model's full answer and every score, the summaries behind the heatmaps, and the paper-style figures and LaTeX tables.